Friday, March 20, 2015

Three unbiased estimators of spike-field coherence

[get notes as PDF]

In these notes we show a simplified expression for the Pairwise Phase Consistency (PPC) measure of Vinck et al. (2010). We illustrate it's relation to a bias-corrected spike-field coherence measure from Grasse et al. (2010), and discuss an third notion of spike-field coherence that is intermediate between the two. 

Here, we use the term "event-triggered" rather than "spike-triggered", because we want to apply these measures to neural events other than spikes (e.g. beta-frequency transients in motor cortex).

Pairwise Phase Consistency

Vinck et al. (2010) define Pairwise Phase Consistency (PPC) as the expected dot product between all pairs of (spike-triggered) phase measurements. 

\[\hat\Upsilon = \frac 2 {N(N-1)} \sum_{j=1..N-1} \sum_{k=j+1..N} \cos(\theta_j - \theta_k)\]

There is an alternative way to express PPC that is faster to calculate, and also reveals a relationship between PPC and similar alternatives. 

Motor cortex LFP spatiotemporal dynamics in a cued grasp with instructed delay task

Update: Portions of these notes have now been published in the Journal of Neurophysiology as  "Dissociation between sustained single-neuron spiking and transient β-LFP oscillations in primate motor cortex" and "Phase reorganization leads to transient β-LFP spatial wave patterns in motor cortex during steady-state movement preparation".

[get notes as PDF]

Task-locked modulations in neural activity

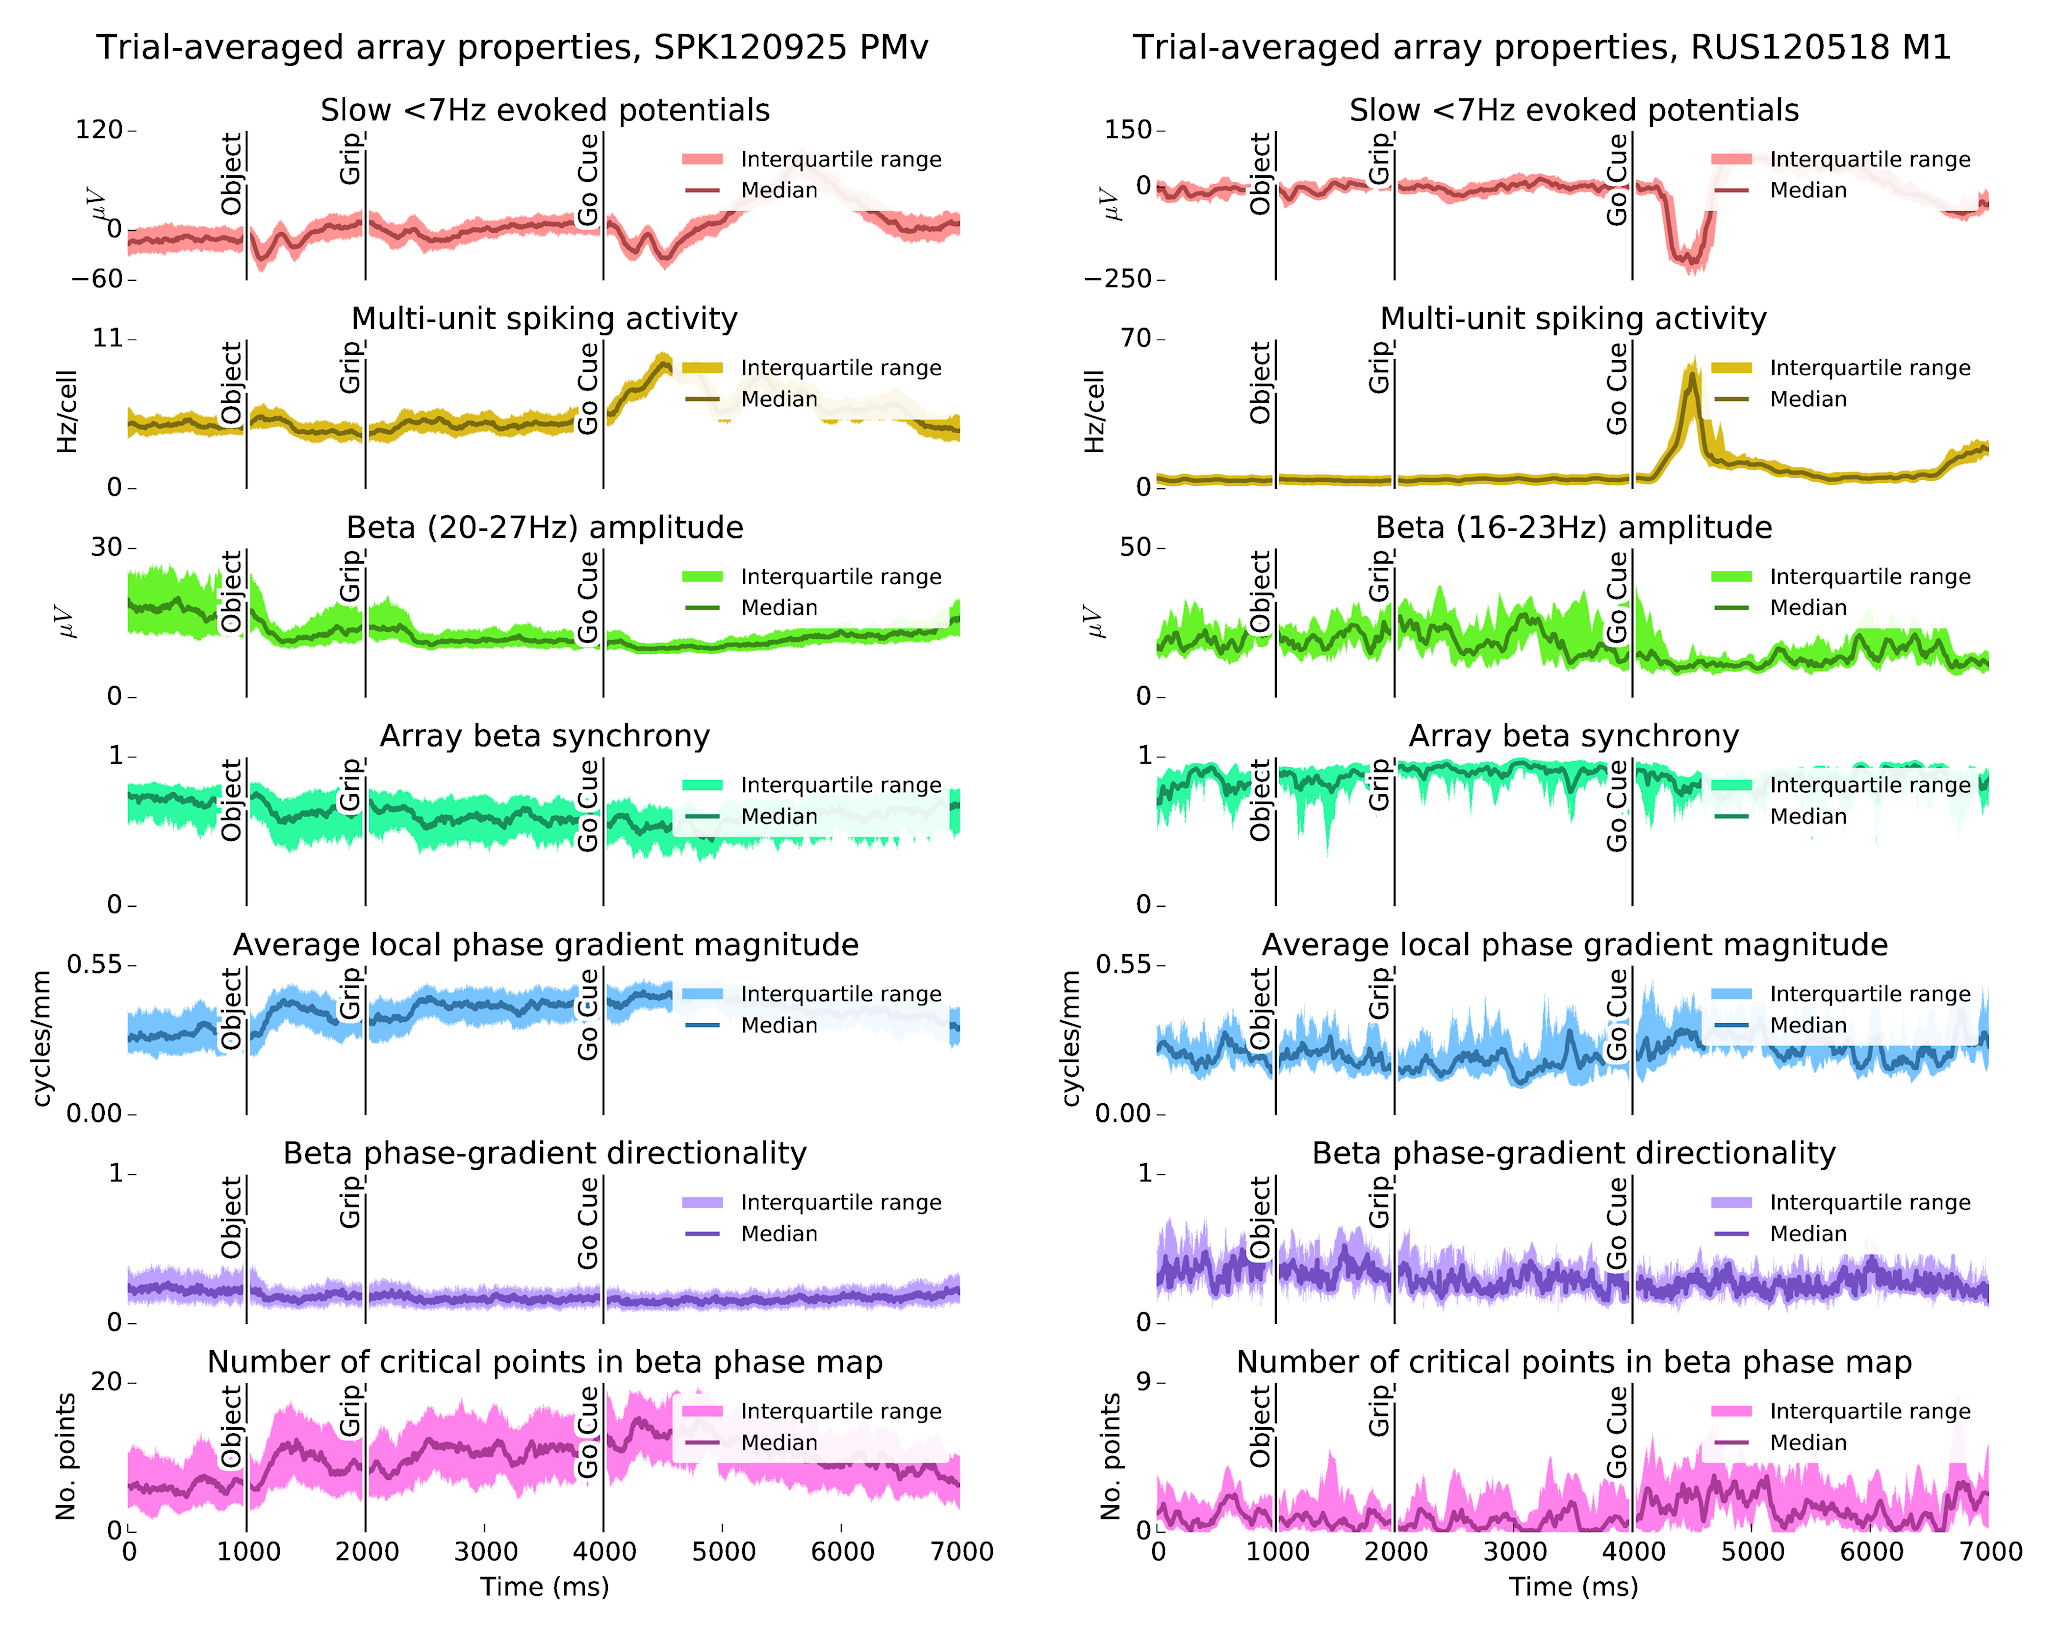
The Cued Grasp with Instructed Delay (CGID) task reliably elicits task-locked activity in all three motor areas (M1, PMd, PMv).

  • Consistent with prior literature, the movement period of the CGID task is marked by slow motor evoked potentials (Fig. 2), increased single-unit firing rates (Fig. 3), and beta suppression (Fig. 4).
  • Beta oscillations are enhanced during the first four seconds of the task, although there are some differences between subjects.
  • The average level of beta-LFP synchrony is correlated with beta-LFP power, and varies across phases of the task.
  • We find no evidence of task-locked phase resetting of beta LFP oscillations
  • The spatiotemporal structure of beta-LFP waves is correlated with amplitude and synchrony, with lower amplitudes reflecting more complex wave structures, and higher amplitudes as more synchronous.

figure1

Figure 1: The CGID task reliably elicits evoked potentials, which correlate with beta suppression. In subject S, beta power is strongest in the first second before object presentation. In subject R, beta oscillations are more variable, with somewhat stronger power between the grip and go cues. In both animals, high beta power appears to correspond to periods of higher beta synchrony, and larger phase gradient directionality, a measure of how much LFP activity resembles a plane wave. Conversely, increases in the average magnitude of the Hilbert phase gradient, which summarizes how quickly beta phase changes over the array, and in the number of critical points in the Hilbert phase gradient, which summarizes the complexity of the beta spatiotemporal wave patterns, correspond to periods of beta suppression.

Tuesday, September 9, 2014

A mechanism for persistent memory in oscillatory networks

I just finished the Methods in Computational Neuroscience "bootcamp". It was intense, but valuable—I can recommend that any student/postdoc who wants to get started in the field take it. 

For a course project, I extended previous work, which showed that oscillatory drive can excite patterned instabilities in visual cortex. These patterns constitute attractor states that are stabilized by an external oscillatory drive. The project explored the idea that similar oscillation-stabilized attractors might serve as a flexible working memory. 

(Unfortunately, these notes are rather brief and incomplete as I never had the time to write this up properly. )

Selective, short-term maintenance of attractor states is important for working memory in neural systems. Neural networks, however, are typically stabilized by feedback inhibition. The delays in this inhibition lead to unavoidable oscillations. 

This project demonstrate a scenario where the attractor dynamics associated with a working memory are not fixed points, but instead fixed limit cycles embedded within a population oscillation. 

External oscillatory drive, perhaps e.g. an attention signal, can switch such a network from a "read-in" mode, in which the system responds to external input, and a "hold" model, in which the system retains a memory of its past states. These concepts may underlie flexible working memory solutions that can coexist with population oscillations.

To better understand the mechanisms underlying this, we explored a switched piece-wise linear model that captured the qualitative dynamics of the original system. We found that firing-rate nonlinearities with positive curvature are important for allowing a synchronous (non-selective) external signal to excite the asymmetric network states associated with a memory trace. 

[get writeup PDF]

[get presentation slides]

Preview: Figure 4

Figure 4: Many-population generalization of the two-population model of Rule et al. (2011), serving as a working memory. Starting from rest, a stimulus is delivered to the first oscillator (green) for $t\in[300,500)$ ms. We test the stability of this stimulus-driven network response during a hold period $t\in[500,1500)$ ms. Without oscillatory drive (top), the memory fades in a few cycles. Periodic stimulation (bottom) preserves the memory. Rightmost plots show the phase-plane dynamics during the readout period $t\in[1000,1500)$. The top system, without drive, has returned to rest. The driven system shows a stable limit cycle, with higher firing rates in the population that initially received the stimulus.

Saturday, June 29, 2013

Invent-abling: enabling inventiveness through craft

This latest paper, "Invent-abling: enabling inventiveness through craft", is a departure from the usual science.  

For the outreach component of the NHS Graduate Research Fellowship Program, and I've teamed up with Deren Güler to explore ways to make early STEM education more engaging and accessible for a diverse array of young people. 

We've been running workshops that merge electronics educational lessons with crafting—origami, sewing, etc. The idea was that STEM education disguised as arts-and-crafts would engage children of all genders and diverse backgrounds more equally. We felt that this would be a more natural and accessible, in contrast to simply, say, making pink breadboards. 

We learned a lot, especially about circumventing biases and preconceptions concerning gender identity and patterns of play. The hands-on and open-ended approach of these workshops was also inclusive of children with differing skill levels. We presented what we've learned at the 12th International Conference on Interaction Design and Children, as a conference paper [PDF]. You can cite it as: 

Guler, S.D. and Rule, M.E., 2013, June. Invent-abling: enabling inventiveness through craft. In Proceedings of the 12th International Conference on Interaction Design and Children (pp. 368-371). 

The plan for the future is to establish a LLC to produce the lesson materials and components, and provide these materials to educators who wish to host similar workshops.

Edit, circa 2019: Epilogue

Thanks to Deren's dedication and persistence, this outreach program has grown into a full-fledged company, Teknikio. Teknikio provides both individual kits and classroom kits for educators. In the years since the first workshops, we've developed new workshops added many more re-usable components for kids to incorporate into their inventions.

The Gordon and Betty Moore Foundation SPARK Award was instrumental in providing start-up capital. In 2018, Teknikio received an NSF Small Business Innovation Research (SBIR) phase I grant to prototype an Internet-of-Things (IoT) kit for the classroom. In 2019, this grant was extended to a phase II award to begin commercialization. Great things start small.


Monday, April 22, 2013

Calculating the AUC for Poisson GLM models of deconvolved spike-train data

These notes provide a function for calculating the AUC for a Poisson regression that works when the spike counts are given only up to some (unknown) normalization constant. Skip to the end for the Python code.

Poisson regression and point processes

Neuroscientists use Poisson regression (in the continuous limit: Poisson point process ) to assess the correlation between neuronal spiking and other experimental covariates. These models are well suited to the scenario in which spikes are binary all-or-nothing events, recorded based on electrical potentials.

The area under the receiver operating characteristic curve

It is common to assess the performance of a Poisson GLM using the Area Under the receiver-operator-characteristic Curve (AUC) .

Definition of the AUC: The AUC is defined as the probability that a randomly-sampled (true-negative, true-positive) pair will be correctly ranked by the predicted firing-rates. We can calculate it by integrating over all such pairs. We will work in continuous time $t\in[0,T]$ for an experiment with duration $T$.

Denote the sets of true positives and true negatives as $t_p\in\mathcal T_p$ and $t_n\in\mathcal T_n$, respectively. Consider a generic model $\lambda(t)$ which predicts the spiking probability at time $t$. Generically, the AUC can be calculated by integrating over all pairs $(t_p,t_n)$ of positive and negative examples:

\begin{equation} \begin{aligned} \text{AUC}(\lambda,\mathcal T_p,\mathcal T_n) &= \Pr\big\{ \lambda(t_n) < \lambda(t_p) \text{ for }t_n\in\mathcal T_n \text{ and }t_p\in\mathcal T_p \big\} \\ &= \frac{1}{|\mathcal T_n|} \frac{1}{|\mathcal T_p|} \int_{t_n\in\mathcal T_n} \int_{t_p\in\mathcal T_p} \delta_{\lambda(t_n)<\lambda(t_p)}, \end{aligned} \label{auc0} \end{equation}

[auc0]

where $\delta_{u{>}v}$ as an indicator function, which is $1$ if $u{>}v$.

Why use the AUC?

Because it depends only on the relative ranks of predicted firing rates, AUC is insensitive to errors in predicting a cell's mean rate, firing-rate variance, or any other strictly increasing transformation of the true rates. These properties make the AUC a desirable performance metric if we only care how well a GLM predicts neuronal tuning in a very general sense. It can be viewed as a type of nonlinear (rank) correlation between the test data and model predictions.

Calcium imaging yields fractional spike counts

Calcium fluorescence imaging has emerged as a standard method for simultaneously recording from large populations of neurons. Since calcium concentrations change relatively slowly following spiking, spike times are recovered indirectly by deconvolving calcium fluorescence signals.

These time-series of deconvolved spikes are sparse, with most entries zero. However, when spikes are detected, they are often detected with a fractional (non integer) value. This introduces some subtleties when working with point-process models, which are defined in terms of all-or-nothing (integer) events.

In practice, non-integer spike counts are no issue for the Poisson regression. Although a rigorous definition of the Poisson distribution is defined only on integers, it can be evaluated for any non-negative real number. This is technically improper, but works just as well and is commonly used in quasi-Poisson regression .

However, integrating commonly used measurements of model performance with fractional spike counts is slightly more subtle.

The AUC for continuous-time spiking data

For spiking data, the "true positives" are the spike times, and the "true negatives" are times when a neuron does not spike. We will work in continuous time, in which a spike train can be treated as a sum of delta distributions at each spike time, $y(t) = \sum_{t_s\in\text{spike times}} \delta(t-t_s)$.

In this continuous case, the duration of spikes is infinitesimal. This means that the set of true positives (i.e. times containing a spike) is of measure zero, compared to the measure of the time-duration of the experiment. In other words, the probability that a given time-point $t_n$ corresponds to a true negative, $\operatorname P_{t_n\in\mathcal T_n}$ is effectively $1$. True negatives are therefore uniformly distributed, with $\operatorname P_{t_n=t | t_n\in\mathcal T_n}= 1/T$.

In contrast, the true positives are a discrete set of $K = |\mathcal T_p|$ spikes, turning the second integral in $\eqref{auc0}$ into a sum. For a continuous spiking time-series, the AUC in $\eqref{auc0}$ can then be written in terms of the spike times $t_k\in\mathcal T_p$, $k\in\{1,\dots,K\}$ as:

\begin{equation} \begin{aligned} \text{AUC}(f,\mathcal T_p) &= \frac{1}{TK} \int_{t_n\in[0,T]} \sum_{k=1}^K \delta_{\lambda(t_n)<\lambda(t_k)} \\ &= \frac{1}{TK} \sum_{k=1}^K \int_{0}^{T} \delta_{\lambda(t)<\lambda(t_k)} \,dt. \end{aligned} \label{auc0b} \end{equation}

[auc0b]

The AUC for deconvolved spikes

Deconvolved spikes from fluorescence data do not recover the true spikes counts $y(t)$, only a non-negative time-series $y(t)$ that is proportional to them (and is not quantized).

This is no problem in practice. To compute the AUC, we only need the density of true positive events per unit time, not their absolute number. The density of true positives per unit time is simply $y$ divided by its sum:

\begin{equation} \begin{aligned} \Pr(\,t_p{=}t \,|\, t_p{\in}\mathcal T_p\,) = \frac {y(t)} {\int_{dt} y(t)} \end{aligned} \label{pt} \end{equation}

[pt]

To calculate the AUC, we could sample $t_n\in\mathcal T_n$ uniformly over $[0,T]$, and sample $t_p\in\mathcal T_p$ using the normalized deconvolved spike counts, $p_t$. We can compute the expectation of this sampling exactly by integrating over the joint distributions of true positives and negatives.

\begin{equation} \begin{aligned} \text{AUC}(\lambda,y) &= \frac 1 {T \int_{dt} y(t)} \int_0^T y(t_p) \int_0^T \delta_{\lambda(t_p){>}\lambda(t_n)} \,dt_n\,dt_p, \end{aligned} \label{auc1} \end{equation}

[auc1]

We'd like to transform this equation into a nicer form, getting rid of that $\delta$ and producing something we can type into the computer.

Define $\operatorname s(t) \in [0,1]$ as the relative rank-ordering of $\lambda(t)$, which starts at 0 for the smallest $\lambda(t)$, and counts up to $1$ for the largest $\lambda(t)$:

\begin{equation} \begin{aligned} \operatorname s(t) &:= \frac {\text{rank of $\lambda(t)$}} {T} = \frac 1 T \int_0^T \delta_{\lambda(t){>}\lambda(\tau)}\,d\tau \end{aligned} \label{s} \end{equation}

[s]

Using $\operatorname s(t)$, we can write the AUC as defined in $\eqref{auc1}$ as:

\begin{equation} \begin{aligned} \text{AUC}(\lambda,y) &= \int_0^T p(t) s(t)\,dt \end{aligned} \label{auc2} \end{equation}

[auc2]

In discrete time, $\eqref{auc2}$ reduces to an average of the ranks $s_t\in[0,1]$, weighted by the deconvolved spike counts $y$. Here it is in Python:

def auc(λ,y):
    '''
    Area Under the ROC Curve (AUC) for deconvolved spike data. 

    Parameters
    ----------
    λ: 1D np.float32, length NSAMPLES
        Predicted scores for each datapoint
    y: 1D np.float32, length NSAMPLES
        Estimated spike counts for each datapoint

    Returns
    -------    
    AUC: float
        Area under the receiver-operator-characteristic curve. 
    '''
    # Cast to numpy arrays
    λ   = np.array(λ).ravel()
    y   = np.array(y).ravel()

    # Ignore NaNs
    bad = ~np.isfinite(λ)|~np.isfinite(y)
    λ   = λ[~bad]
    y   = y[~bad]

    # AUC is undefined if there are no positive examples
    d   = np.sum(y)
    if d<=0: return NaN

    # Density of true positives per timepoint
    py  = y/d

    # Convert scores to fractional ranks
    rs  = scipy.stats.rankdata(λ)/len(λ)

    AUC = np.average(rs,weights=py)
    return AUC

Tuesday, March 12, 2013

Quasi-Poisson regression

In neuroscience, we often model the number of spikes observed from a neuron as a Poisson distribution with rate $\lambda$:

\begin{equation} y \sim \operatorname{Poisson}(\lambda) \end{equation}\begin{equation} \Pr(y|\lambda) = \tfrac 1 {\Gamma(y+1)} \lambda^y e^{-\lambda} \end{equation}

In a typical log-linear Poisson Generalized-Linear Point-Process (PP-GLM) regression, we estimate the logarithm of $\lambda$ as a function of other, measured covariances "$\mathbf x$", that is $\ln\lambda = \mathbf w^\top \mathbf x$. However, for these notes we will simply assume that $\lambda$ is already available, and we'd like to model $\Pr(y|\lambda)$.

Over- and Under-dispersion

One limitation of the Poisson distribution is that it has only one parameter, $\lambda$, which controls both the mean $\mu=\lambda$ and the variance $\sigma^2 =\lambda$. However, spike-count data are often over- or under-dispersed in practice, meaning that the variance might be larger or smaller than $\lambda$, respectively.

There are many way to model over-dispersed data. For example, using the Negative Binomial distribution is common. It is also possible to use the "zero inflated Poisson distribution". In this case, the probability of observing any spikes at all is controlled by another Bernoulli ($s = \operatorname{Bernoulli}(p)$) variable, and the distribution of spike-counts given $s=1$ is then Poisson distributed. Both of these approaches can only increase the variance, so they can only handle over-dispersion.

Quasi-Poisson observation model

Another approach to handling over/under dispersion is the so-called "quasipoisson" regression. This uses a function for $\Pr(y|\lambda)$ which is not a probability density function. Nevertheless, it provides a quick and useful hack to control the dispersion without changing much in the Poisson regression.

To adjust the dispersion in quasipoisson regression, one can multiply both the observed spike counts $y$ and the firing rate $\lambda$ by a dispersion-control parameter "$\kappa$".

\begin{equation} Q(y|\lambda) \approx\tfrac {\kappa} {\Gamma(\kappa y+1)} {(\kappa\lambda)}^{\kappa y} e^{-{\kappa\lambda}} \end{equation}

On the surface, this corresponds to a new Poisson distribution with rate $\lambda' = \kappa\lambda$, so its mean and variance are $\mu'={\sigma'}^2=\kappa\lambda$. However, we evaluate it at $\tilde y = \kappa y$ rather than $y$. This makes this an improper distribution for discrete, integer-value count data.

Adding a scale parameter to an existing distribution

Recall: If $x\sim P(x)$ is a continuous, one-dimensional random variable with known distribution "$Q(x)$", then the distribution of $\tilde x=2x$ is narrower. In particular

\begin{equation} \tilde x \sim 2\cdot P(\tilde x = 2x) \end{equation}

The multiplication by 2 adjusts the normalization factor to account for the fact that a function that is half as wide also has half as much area, so we need to multiply by 2 to ensure that the density still integrates to 1. If $x$ has known mean $\mu$ and standard deviation $\sigma$, then the rescaled $\tilde x$ will have mean $\mu/2$ and $\sigma/2$, respectively.

Scaling of observation error variance in the quasi-Poisson model

So, when we multiply our rate $\lambda$ by $\kappa$, we move the mean and variance to $\mu'={\sigma'}^2=\kappa\lambda$. But, by evaluating this density at $\tilde y=\kappa y$, we then divide the mean and standard deviation by $\kappa$. The net transformation leads to

\begin{equation} {\tilde\mu} = (\kappa\lambda) / \kappa = \mu = \lambda \end{equation}\begin{equation} {\tilde\sigma}^2 = (\kappa\lambda)/\kappa^2 = \lambda/\kappa \end{equation}

We see then that $\kappa$ controls the over/under dispersion. $\kappa=1$ is the original Poisson distribution. $\kappa>1$ reduces the variance. $\kappa<1$ increases it.

Log-likelihoods

The log-likelihood for the quasi-Poisson model is

\begin{equation}\ln Q(y|\lambda) =\ln(\kappa)-\ln\Gamma(\kappa y+1) +(\kappa y) \ln(\kappa\lambda)-\kappa\lambda \end{equation}

If $k$ is known and $y$ is fixed, we can instead optimize

\begin{equation}\ln Q(y|\lambda) =\kappa [y \ln(\lambda) - \lambda] + \text{constant} \end{equation}

In this case quasi-Poisson regression can be thought of as Poisson regression, but with an extra "fudge" factor $\kappa$ that re-weights the importance of our evidence.

Take care

Care must be taken when mixing the quasi-Poisson observation model with Bayesian methods. For the most part, things will work. However, since the quasi-Poisson model is not a distribution, it is unclear how it should be normalized. In particular, estimating $k$ rigorously is not well-posed. I suppose one might attempt to e.g. adjust $k$ to maximize and evidence lower-bound, retaining then the terms $\ln(\kappa)-\ln\Gamma(\kappa y+1)+y \kappa \ln(\kappa)$ from the quasi-Poisson likelihood that depend on $k$. I have not tried this, but perhaps it usually works out ok.

Wednesday, January 16, 2013

Impact of redundancy on stable decoding

[get notes as PDF]

Neural activity is redundant: many states in motor cortex can generate similar movements. When we record from motor cortex, we capture only a small fraction of the total neurons. Redundancy makes it possible to observe the overall state of motor cortex from limited observations, but might also impair the generalization performance of a linear decoder.

Consider two neurons, $A$ and $B$, that combine linearly to produce movement $C{=}\alpha_1 A{+} \alpha_2 B$. (Perhaps both neurons drive the same targets in spinal cord.) An animal could use any linear combination of activations of units $A$ and $B$ to perform behavior $C$, so long as the sum $\alpha_1{+}\alpha_2$ is constant. What if there is an unobserved variable $\gamma$ that sets whether neuron $A$ or $B$ is used more (Fig. 1)?


Figure 1: (simulated hypothetical scenario) Neural signals $A$ and $B$ combine linearly according to weight $\gamma$ to form behavioral output $C=\gamma A + (1-\gamma) B$. Parameter $\gamma$ modulates sinusoidally between $0.25$ and $0.75$.